Week 5: Reading Reflection

After reading this, I realized the way computers see things is pure math and calculations. They do not have an understanding of things like we humans do. Computers are like blank slates and for them to process anything, we have to program every single step. A computer cannot detect a person unless a programmer writes math rules to help it spot changes in pixels. I was surprised at how a seemingly simple concept like vision and tracking is actually so much more complex.

I really liked that a lot of the detection in these systems does not come from the code alone, but also from controlling the physical environment. Things like using a plain white background, strong lighting, or high contrast clothing make it way easier for simple algorithms to work well. So it is a process that requires precision both inside and outside of the code. Even a simple change in lighting or shadows can completely confuse the computer.

Also, the duality of this technology is interesting. Computer vision was originally developed primarily for tracking and surveillance. However, it later became a popular tool that artists use in interactive art. Depending on whose hands this technology is in, it can transform from an entertaining experience into something far more invasive or dangerous. It made me realize that as someone who might work with tracking tech in the future, I need to use it carefully and be mindful of where and how I use it.

Week 5 – Reading Reflection

One of the differences I observed was basically the flexibility of human vision compared to computer vision. Generally, we are able to identify people, objects, and occurrences without really thinking about it that much, even when there is a change in lighting and backgrounds. On the other hand, computer vision is dependent on certain conditions and rules. This means that when there is an extensive change in lighting or an object merges with the background, then the computer will not be able to detect it effectively. The reading also helped me understand that computers do not interpret what they are seeing, they just analyze pixels, movement, luminosity and contrast. 

There is one method called background subtraction where the computer compares the current video with a picture of the empty background in order to find out what has been changed. As it was mentioned in the reading, “areas which are very different from the background are likely to represent objects of interest.” In other words, if there is a person appearing in the frame, the computer will be able to identify that some areas of the picture are different from the original empty background and that would make it easier to track its movement. 

I believe that computer vision enhances the interactivity of art since the art piece will interact with your actions in terms of position, movement, and other factors. But at the same time, it can feel a little weird due to the fact that it feels like you are being watched and tracked. I believe that computer vision adds individuality to the experience, since art pieces will react to the actions of each person individually. This brings out the idea of individuality, surveillance, and privacy.

Week 5 Reading Assignment

This week’s reading leans a bit more towards the technical side, and I honestly think that it brings a new perspective to the table about the intelligence of computers. As the reading suggested, “a computer, without additional programming, is unable to answer even the most elementary questions” that humans can! The concept of computer vision is so interesting because I often understand it the way my vision works (looking at the content & understanding it) where in reality, computers process data pixel by pixel, character by character.

The reading also identifies the 3 low-level algorithms that help computers “see:” frame differencing, background subtraction, and brightness thresholding. At this point of the reading, I found myself asking 1) are these techniques used at the same time and 2) how exactly is this different from human vision? Do we also do this in a faster, almost automatic manner that it seems “natural,” or we do process data completely differently?

I especially appreciate the example of Limbotime. By piecing the illustrative photo and the author’s description, the theoretical aspects discussed prior in the reading makes a lot more sense. I also really admire the amount of details that goes into an arguably quite simple game (identification of body, tracking of body, position relative to imaginary lines, etc.)

Despite all of the above, the creepiest part that stood out to me is the issue of surveillance, particularly the project Suicide Box at the Golden Gate Bridge. Overall, surveillance is complicated because it directly interferes with privacy, consent, etc. But for Suicide Box especially, the system is recording very very sensitive and “negative” scenes. It’s also notable that in the same period, the system counted 17 instances of suicide, while official reports had 13. Does this suggest that the system has flaws with its vision and identification? Could it mistaken humans and other objects? Or is it so accurate that it reveals the flaws of official reports? I think it’s so disturbing and creepy overall, but this reading definitely confronts the potential dangers and unethical aspects of computer vision that I overlooked.

Week 5 Reading

To my mind, the difference between computer vision and human vision lies in the situational awareness. Take Christian Möller’s Cheese installation as an example. It identifies:

a) whether the person is smiling

b) whether the smile is genuine.

Having said that, computer vision works through identifying emotion with a limited number of factors as opposed to humans, who take things like tiredness, personal matters, body language and other variables when evaluating happiness. Humans are able to build a more comprehensive image of others, because through previous experience they see things that computes may overlook. While reading about the LimboTime and examining the pictures I thought of something else that the computer may not account for. If the person is wearing white and is leaning back, their failure to compete the task may go unnoticed for two reasons: first, the line is invisible and not tangible and second, their the body may not be detected in its entirety. Similarly, if a person is bald, the computer will detect contrast in their face features as the highest point of the body and will shift the results.

Even though those are small errors that may occur they are worth mentioning when the topic is comparing human and computer.

A technique that could help the computer track what we are interested in would be to give more instructions. Instead of asking it to track mouth movement only, we could also add the gradual disappearance of the iris (as a sign of smiling) or a detector for the sound of giggling for example.

I think that computer vision, even though not revealed to its full potential, is a great thing to incorporate in interactive media. Even lower levels of interactivity allow for users to enjoy different products. Humans are simple creatures and they crave entertainment, be it in small amounts. I don’t believe its capacity is going to negatively affect humans or make them unsatisfied.

Week#5 Reading response

Creative reading response:

I think a major difference between computer vision and human vision is the way we process things and how we’re able to process visual information. The computer needs to have recognition ’manually’ set up in order to process the visual data, but humans don’t, we have a built-in innate processor—the brain. Before answering this question, I never really thought about this, because in hindsight, computer vision ‘sees’ things, or else how would there be videos right? Then I realized, no, it doesn’t ‘see’ things, I only assumed so because I see it, but the computer only recorded it as a data, as pixels, it has no concern on the content, in fact, it’s unable to recognize the content unless I define what’s content, which means the specific lighting, color, motions, etc., which again contradicts how we process because this action of ‘defining’ is in of itself restricting and ‘predictory’ already; contents can appear in any light, form, color, and motion. This is quite fascinating to me because this complex machine of a computer can be so precise but still not more precise than our brain, and how I’m able to have vision and recognition without ‘programming’.

Because a computer only recognizes data, we have to manipulate the data it receives and the way it interprets it so that we can display an output that makes it seem like it understood the ‘contents’. That means we need to set up ‘mathematical’ comparisons between the values of pixels and frames, a bigger component of pixels, and specify the kind of values we want to focus on, like a specific color, specific ‘motion’ or a specific brightness. To make it easier for the computer, we can ‘sell-fulfillingly’ manipulate the physical space the camera is placed in to achieve the ‘recognition’ we set up. For instance, if I made the recognition to focus on the difference of brightness, I can make the space all white so that my ‘target object’ can be more easily found because of the intense contrast between the brightness, or I can even make the space ‘illuminated’ so they’re emitting light, which our desired object shouldn’t be able to do, or else there’d be a small slip-up.

This also makes me fascinated in the way surveillance is incorporated into artworks because surveillance/ tracking places a higher demand on the computer since it’s done in ‘secret’ and thus means we can’t manipulate the physical space or the target object but yet surveillance and tracking is still existent, and even used in interactive art. I wonder if that ‘shortcoming’ helps make the art or are they sufficient enough? I don’t know, because intuitively, we always want to have better and more intelligent and upgraded devices, but sometimes artists would purposefully find ‘outdated’ and abandoned things to make their point so I guess my opinion is that while the physicality of devices and equipments affects a lot on the work, it’s not a determining factor to ‘artistic expression’ in the sense that anything less of the best would not make art, which I think is why people like Myron is still able to make something as good as videoplace in a time ‘tech’ wasn’t that prevalent.

Midterm Project: Progress Report

Concept

For this project I wanted to make a cafe game. The premise: the player works the night shift at a cafe that’s open 24/7. Because of this, the customers they get are a bit more unusual, both in appearance and behavior (ghosts, skeletons, wizards, etc). Instead of asking for specific items like a latte or an espresso, they describe their mood and the kind of drink they’re looking for, and the player has to figure out what they actually want.

Each ingredient has mood tags: energizing, bold, calming, comforting, mild, sweet, and refreshing. Each customer secretly wants certain tags. When the player serves a drink, the game checks how many of the customer’s tags were met. If all of them are met, the customer is happy; if only some are met, they give an okay reaction; and if none are met, they’re disappointed. The better the drink, the bigger the tip.

User Interaction

  • Title screen: Start, How to Play, and Settings (where music can be turned on or off)
  • Cafe: a customer appears with their order in a speech bubble. Clicking the bubble takes their order.
  • Kitchen: the player clicks up to 3 ingredients to add to the cup. The layers blend together in the cup as they’re added. Clear empties the cup, and Serve finishes the drink.
  • Reaction: back in the cafe, the customer sips the drink and reacts, the tip goes into the tip jar on the counter, and the clock moves forward an hour.
  • End of shift: after 5 customers, the sun starts to rise and the shift is over. The end screen shows total tips, with options to Play Again or go Back to Main.

Design

I’m using a gameState variable to switch between screens (title, instructions, settings, cafe, kitchen, end), and a resetGame() function that resets the tips, clock, and customers so a new shift can start without restarting the sketch.

The main classes are:

  • Ingredient (name, color, tags): display() draws it on the counter, and isHovering() checks if the player is hovering over or clicking it.
  • Cup (x, y, ingredients, max of 3): add() adds an ingredient if there’s room, clear() empties it, and display() draws the cup and blends the ingredient colors into layers.
  • Customer (name, order, wants, reactions): display() draws the character and their speech bubble, score() counts how many wanted tags are in the cup, and serve() scores the drink and starts a timer for the reaction.
  • Button (x, y, label): display() and isHovering(). Used for Start, How to Play, Settings, Clear, Serve, Play Again, and Back to Main.

Uncertainty

Personally, the part I was most worried about was the visuals. I felt the classes and logic would work out with trial and error, but making the game actually look good and cohesive would take more effort.
I initially tried looking for character sprites. However, the only viable option had to be purchased. In addition, the characters were drawn in a pixelated style, I was worried that this wouldn’t match the vibe of a hand drawn backdrop. So instead, to ease this worry, I decided to draw each character myself.
Here are the characters:

Finding a backdrop was also a struggle, but I eventually found one on Magnific cafe image. Its simple, cartoonish style matches the characters well. To make it feel like the night shift, I will add a dark overlay in p5 that slowly warms toward a sunrise color as the night goes on.

Reading reflection – Week #5

After completing the reading, I now understand the many ways in which computer vision differs from human vision. More specifically, computer vision tends to rely on the observation and analysis of pixels on a screen, whether it is through comparing frames, brightness of pixels, or their overall movement. Unlike humans, a computer does not automatically understand the meaning behind what it sees. Instead, it needs specific features to be identified and tracked through an algorithm. This means that even something that seems obvious to a human, such as recognizing different people or understanding their expression, can be a difficult task for a computer. As a result, interactive art requires very controlled variables and environments in order for computer vision to be useful. An example shared in the reading was the game LimboTime. This was only able to work because the game took place in front of a white screen, allowing the programmers to use brightness-based thresholding to distinguish the players from the background. This has me thinking about how much of the “vision” in computer vision actually depends on the artist designing the environment around the technology. Rather than simply making a program smarter, the artist can make the problem easier by controlling the lighting, colors, and background. This is quite interesting to me because it almost reverses the way I normally think about interactive art. Instead of designing the environment entirely for the human to experience and interact with, part of the environment has to be designed for the computer as well.

Despite how interesting this topic is, the parts related to surveillance raised some flags for me. It made me realize that not only can computer vision be used for interactive art, but it can also be used to monitor people without their consent. For example, the artwork called Sorting Daemon analyzes people on the street and uses them within the artwork. Whilst the artwork was motivated by the artist’s “concerns about the increasing use of automated systems for profiling people” it made me question if the artist was not playing into the same problem. The artwork is criticizing the use of automated systems to profile people, but it still requires those people to be monitored and analyzed in order to make that criticism. This made me wonder whether the artistic purpose changes the ethical implications of surveillance, or if being used for an artwork without knowing about it is still a form of surveillance regardless of the artist’s intentions.

Week 5 – Reading

Before reading the chapter, I thought computer vision would basically be all about how computers are taught to see the same way as humans. But I quickly realised that it’s much more complicated than that. I found this very interesting because when humans view an image they see it as a general, full picture  thing. Us humans can understand what we are seeing and can identify it. Meanwhile a computer receives the image as pixels without knowing what they represent at first. The reading mentioned techniques that the computer programs. Some of those factors include frame referencing, to detect movement, background subtraction, to separate a person or object from the background, and brightness thresholding, to know the difference between lighter or darker things compared to their surroundings. By the end of the reading, I concluded that computer vision feels less like giving a computer human eyes and more like giving it specific rule for what it should pay attention to.

What caught my eye the most was how these tracking abilities can completely change interactive art. Computer vision can allow the viewers movement or position or even facial expressions to be become part of an artwork. Furthermore, someone can interact without using a mouse or keyboard. This reminded me of a field trip that I went to last year during comms lab. We went to team lab and interacted with so many exhibitions. One that came to mind is an artwork where it recognised our silhouettes and movements and made our bodies interact with the projected graphics on the wall or on the floor. I think this creates a much more immersive type of interaction because the artwork is technically communicating and responding to the person standing in front of it.

On the other hand, it’s still feels a bit uncomfortable thinking about how easily the same technology can become surveillance. The reading mentioned that computer vision can track people who willingly participate but can also observe people who may not even realise they’re being watched. A personal example that happens in our day-to-day life is our phones. Not only does it use face recognition to open our phones but some phones have the ability to see how close the phone is to your face, and will then notify the user to back away. So from what I gathered, computer vision can be either playful and creative but also makes me question privacy in a way. It makes me wonder how much information a computer should really be allowed to collect about us.

Week 5 – Reading Reflection

One thing I found interesting is that computers dont really “see” things the same way we do. When we look at someone, we can understand that they are a person, what they are doing, and what is happening around them. A computer, on the other hand, is basically looking at pixels and needs specific ways to detect things like movement, brightness, or changes in an image. This reminded me of all the games I used to play when I was younger that used cameras to track your movements, like Kinect Adventures on the Xbox. I remember having to stand in a certain area so the camera could see my full body, and then my movements would control what was happening in the game.

Thinking about how those games were able to track us also connected to the different techniques mentioned in the reading. The computer can look for movement between frames, separate someone from the background, or use differences in brightness to figure out what it needs to track. The reading also talks about how things like lighting and contrast can make this easier. This also reminded me that in some games, the camera would not track you properly if you were standing in the wrong place or the room was not set up well.

But that ability to track people also made me think about the other side of computer vision. Tracking can make interactive art really fun because, like those games, your actual body can become part of the experience. At the same time, the surveillance examples in the reading made me realize that the same ability to track someone’s body and movements can also be used to watch them without them really knowing. I think there is a big difference between choosing to be tracked because you are playing a game or interacting with an artwork and being tracked without knowing that it is happening.

Week 5 Midterm Project: Idea & Progress Documentation

My concept

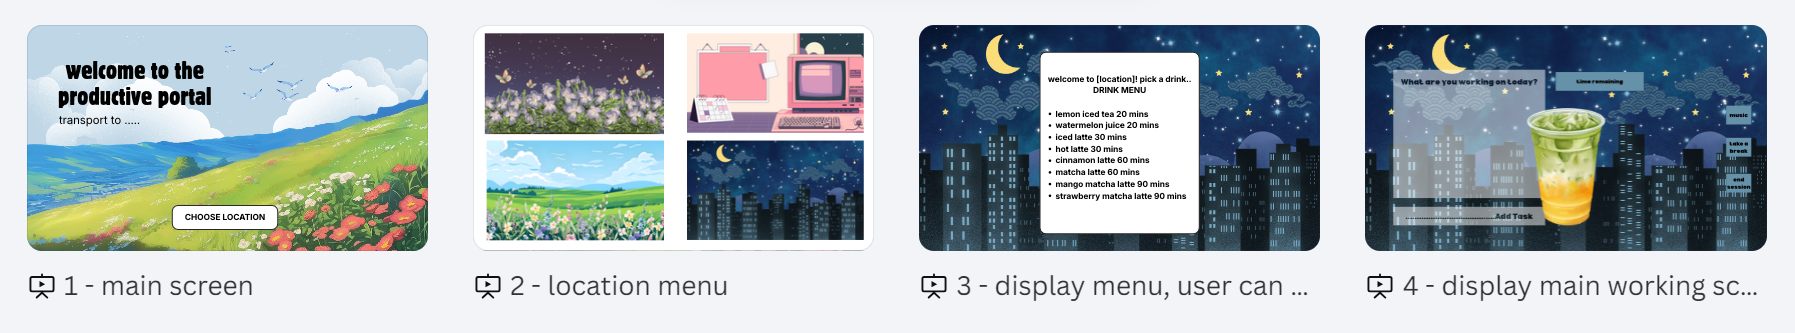
For my midterm project, I plan to build an experience called “productive portals.” Basically, it’s a work/study with me experience where the user and choose a portal to transport to, and the program will have creative interactions (explained below).

The home screen provides a brief description of the experience and a button that says “choose portal”. When clicked on, 4 portal options pop up, and the user gets to choose 1 of 4 portals.

This takes the user to the study location they chose. A “drinks menu” pop up, where the user can choose from a variety of drinks. The fancier the drink is, the longer the work timer is (for example, if they choose a strawberry matcha, they will work for 90 minutes).

After this, they will enter the main working screen. The main working screen contains an illustration of the drink they chose, a timer counting down, and a to-do list where the user can add the tasks they need to complete. There will also be 3 buttons on the side:

  • End session: the study session will end and takes the user back to the home screen
  • Pause: timer will pause
  • Music: choose 1 of 4 or 5 ambience background music
a wireframe design on Canva…

Structure and Implementation

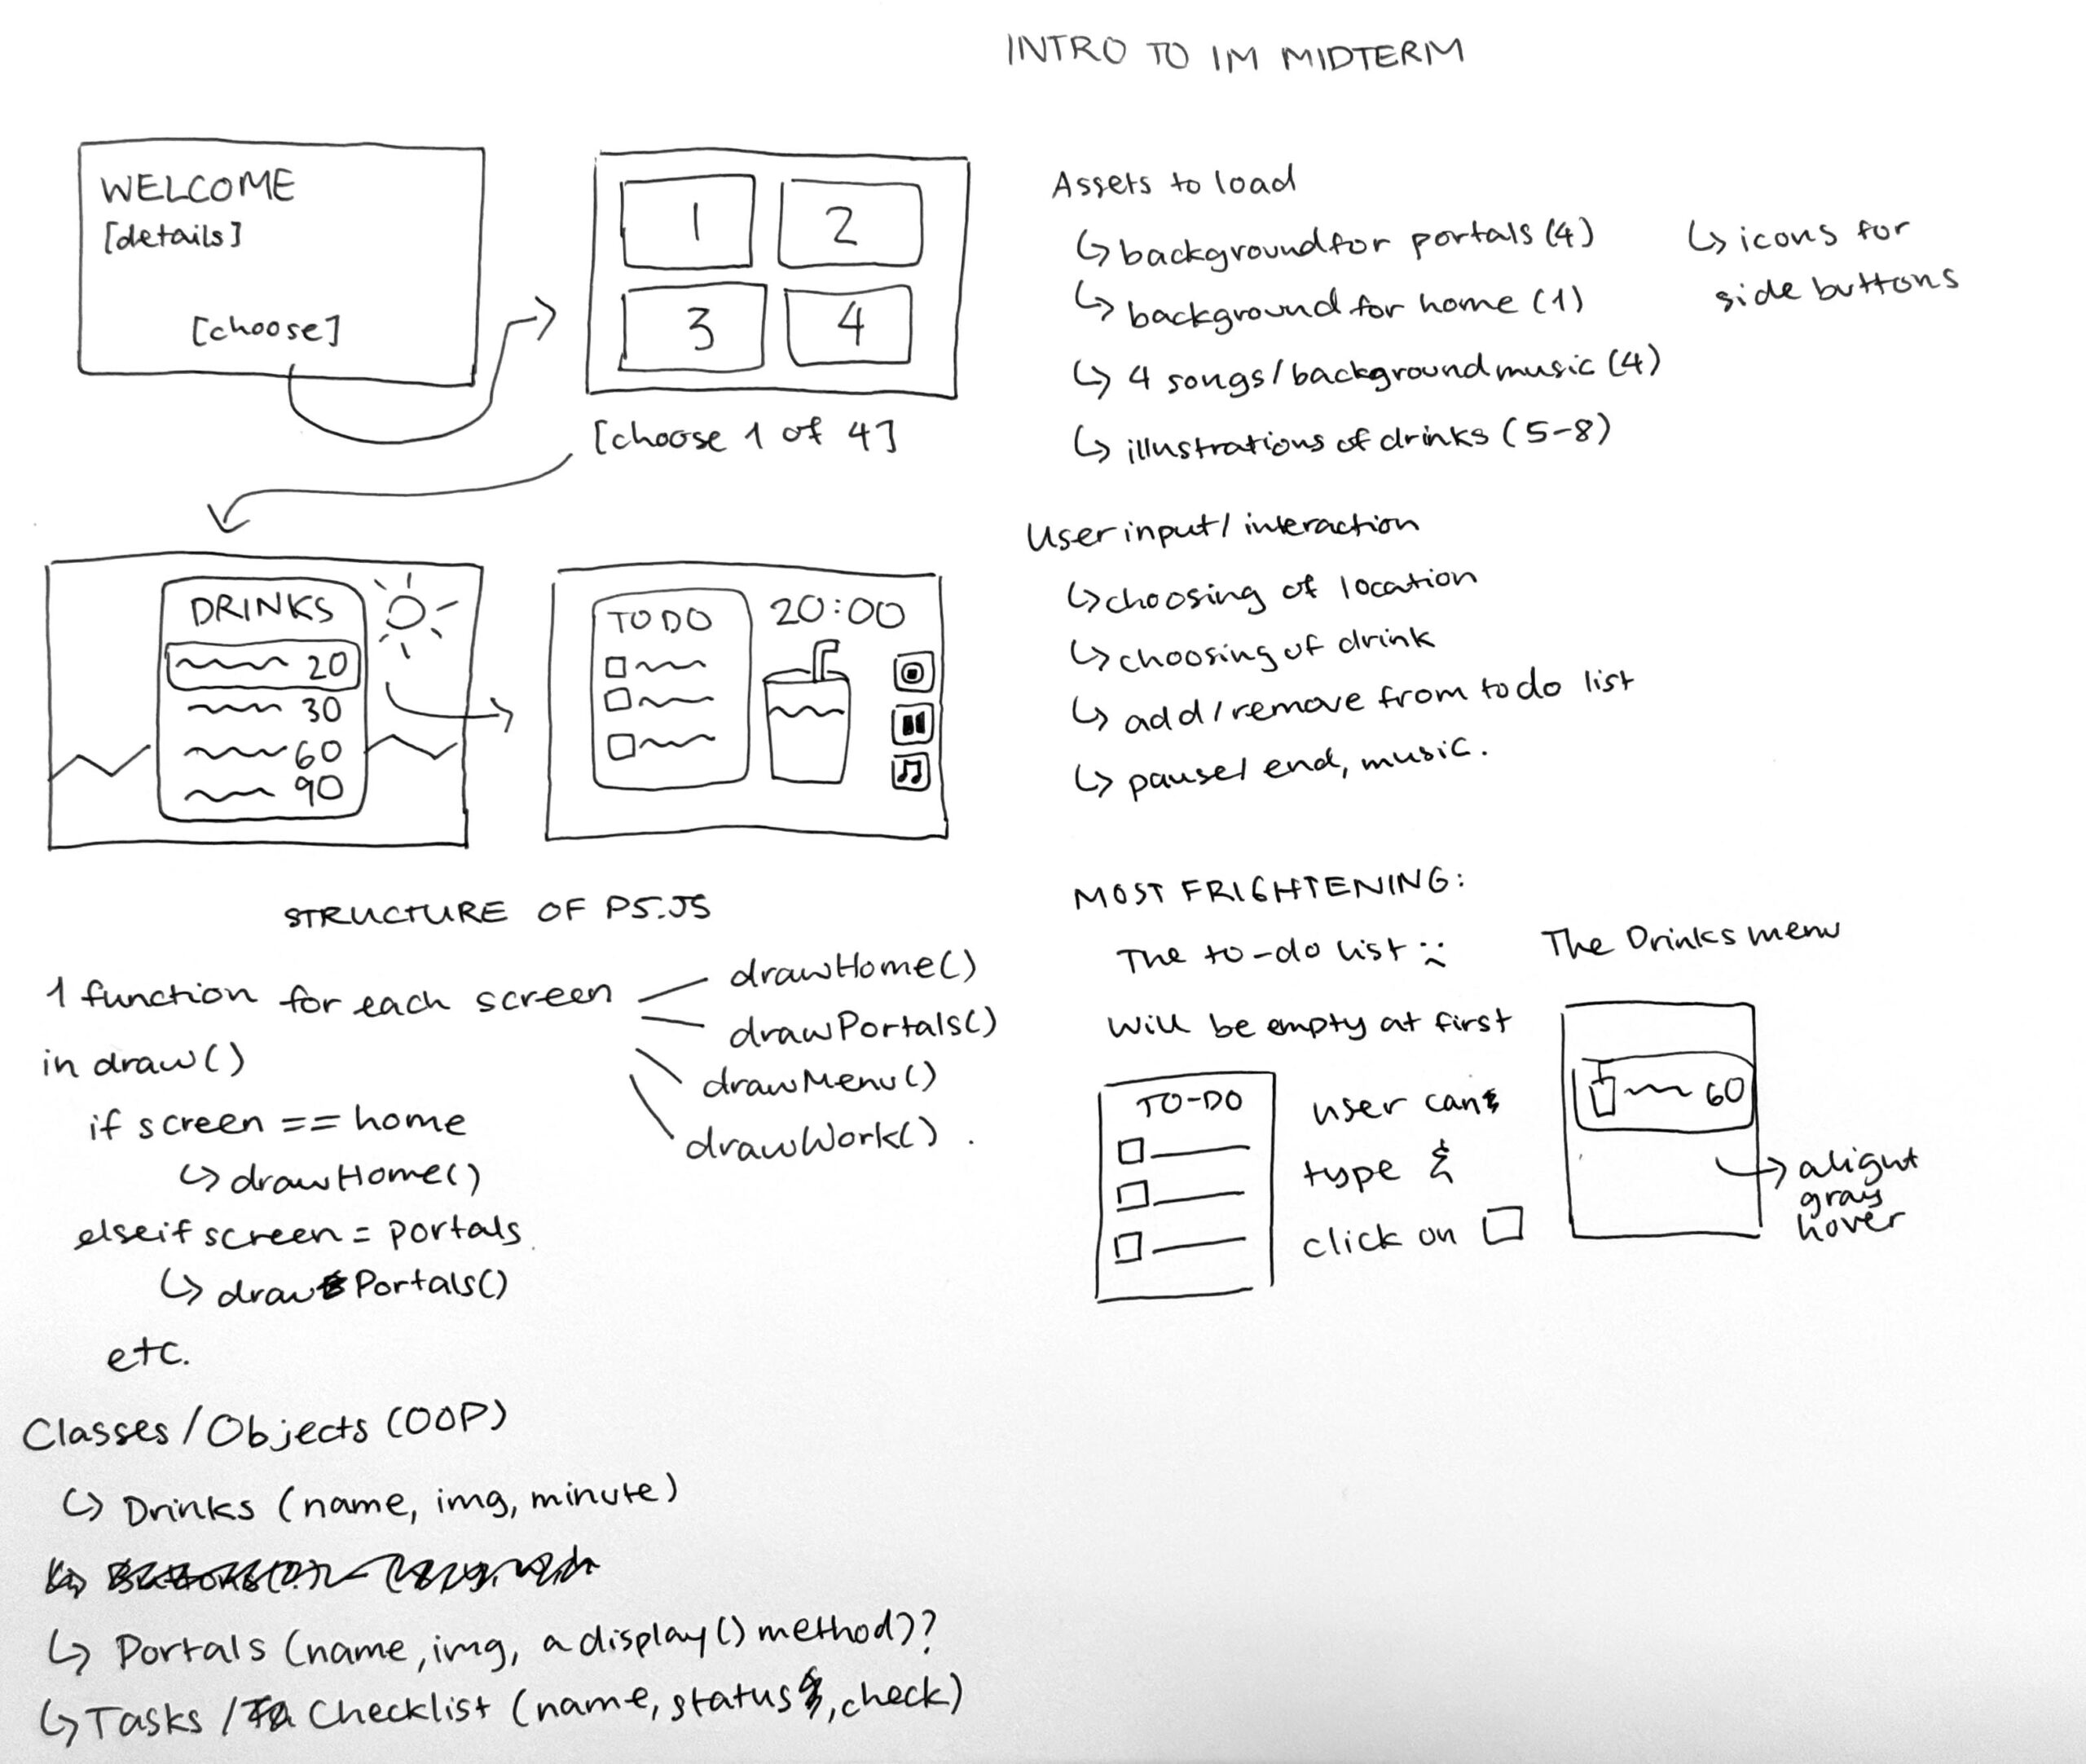
I also plan to use OOP and create classes for Drinks, Portals, and Tasks. I’m not entirely sure yet…!

The user will mainly use mouse-press for interaction that requires decision making, and they will need to type with keyboard to enter tasks into the to-do list.

The most intimidating portions for me are the to-do list and the menu, I also found some resources that I think would be helpful to look at:

Demo version

I created a demo version which contains the structure of the first 3 screens (including the menu): see code; see full screen.
Note: since this is the demo version, my only focus was the structure and functionality. In other words, please disregard the aesthetics :))